09/11/2026 // LLM Research
Best LLM for coding in 2026: Fall
Fall update to my coding LLM rankings. OpenAI Astra is a different class on intelligence and wide work, and last on usage. Grok 4.6 is still the daily driver.
Late summer had Grok at the top of usage, intelligence, and wide work. Fall split that.
If you ask me what the best LLM for coding is in fall 2026, I still don’t have one name. I have a model that is too good and too expensive, and a workhorse that lies to me all day with enough tokens to recover.
Same three dimensions as June and August. Usage allowance, top intelligence, wide problem handling. Open source still gets its own list.
They still don’t overlap. This time they barely even point at the same product.
Ranking by usage allowance
This is still the list that decides what I open for a full day.
My current ranking:
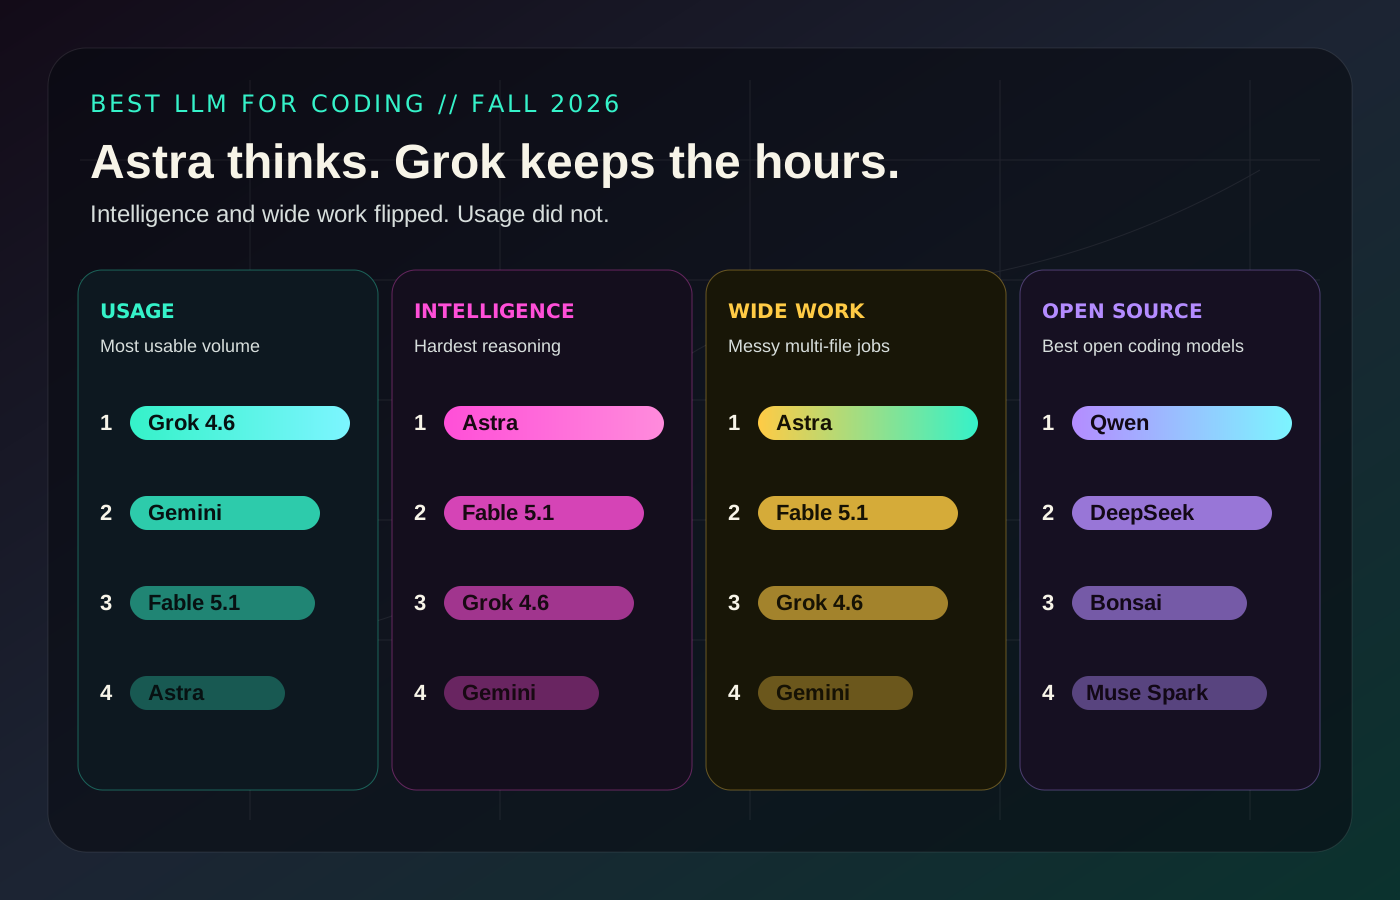
- Grok 4.6
- Gemini
- Fable 5.1
- Astra
Grok is first, and it is not close. Unlimited enough that I stop counting. That is the whole product for daily work.
Gemini is next. Better room than Anthropic or OpenAI for how I actually spend a week.
Fable 5.1 is second last. Anthropic’s, and I feel the bill.
Astra is last. OpenAI’s new one, and obscenely expensive. I use it, then I get off it.
Ranking by top intelligence
Hard problems. Real constraints. The model has to hold the codebase, not invent a clean story over it.
Current ranking:
- Astra
- Fable 5.1
- Grok 4.6
- Gemini
OpenAI Astra is not a small step on this list. It is a different class. Jobs the others grind on, it just does. GPT Sol was the OpenAI name I had near the top in August. Astra replaced that slot and then some. I have been calling it #1 in my head for a few weeks and the ranking has not wobbled.
Anthropic Fable 5.1 is the next best thinking model I have. The one that used to sit next to Opus 5 in my mix. Careful, strong, still behind Astra.
Grok 4.6 is third. Smart enough to be the daily driver. Not Astra.
Gemini is last here. I still use it. I do not pick it when the problem is actually hard.
Ranking by wide problem handling
Messy jobs. Lots of files. The thread has to survive while you iterate.
Current ranking:
- Astra
- Fable 5.1
- Grok 4.6
- Gemini
Same order as intelligence. That is the fall headline for me: the smartest model is also the one that holds a wide job together, and it is the one I can least afford to leave running.
Astra on a sprawling pass is the best I have used. The catch is you cannot let it wander. You point it, you take the result, you go back to something cheaper.
Fable 5.1 is the Anthropic fallback when Astra is too expensive for that pass.
Grok will take the wide job. It will also invent files, APIs, and whole explanations. You spend the extra turns because you have them.
Gemini is last on this list too.
Astra’s effort curve
This is the part I did not expect.
Astra has the usual effort stack: low, medium, high, xhigh.
On low and medium it wastes tokens. It circles. It retries. It spends like it is lost.
On high and xhigh it gets to the answer faster, and it uses fewer tokens doing it.
That is backwards from how this climb has felt. For years, thinking harder meant a longer trace. More tokens. A bigger bill for the same question, hopefully a better answer.
Astra at the top of the stack is the opposite. More all at once. Less wandering. The expensive settings are the efficient ones.
I don’t have a clean theory. It just keeps happening on real work. Low and medium feel like the model is feeling around. High and xhigh feel like it already has the shape of the answer and is just writing it down.
That is a strange point to pass in the intelligence climb. Not “thinks longer so it costs more.” Suddenly the harder setting is the one that burns less.
It is also why the price is so annoying. The mode you actually want is the one that costs the most per unit, even when the trace is shorter. You are paying for the class of model, not for a long chain of thought.
Astra is a whole class unto itself on this board. It is also hard to work with, because the bill shows up before the magic starts to feel routine.
Grok 4.6 is the workhorse
I live in Grok.
Unlimited tokens, or close enough that the meter is not the constraint. That is rare and I am not giving it up.
It hallucinates like crazy. Paths that do not exist. Functions it invented. Confident patches that do not compile. You cannot trust the first pass.
The only reason that is tolerable is the allowance. I can make it read the file again, run the build, check the diff, and keep going. On a tight-meter model, that loop is how you run out of budget. On Grok, that loop is the job.
So Grok is not my smartest model. It is the one I can afford to be wrong with.
Late summer I had Grok at the top of all three closed lists. Fall knocked it off intelligence and wide work. It kept the hours. That is still the more useful win for most weeks.
Open source
This list got more crowded.
- Qwen
- DeepSeek
- Bonsai
- Muse Spark
Qwen is still first among the open models I use for coding. DeepSeek is in the mix in a way it was not for me in August. Bonsai and Muse Spark are on the board now.
They are not beating Astra. They are not Grok on volume either. They are good enough that open source is not a side note, and there are more names worth keeping around than there were in June.
How this plays out in practice
I still mix tools. The mix got more annoying.
Daily volume: Grok 4.6. Expect hallucinations. Budget the extra turns. You have them.
Hard problem I actually need right: Astra at high or xhigh, then get off it. Fable 5.1 if the Astra bill is not worth it for that pass.
Wide work: same split. Astra if I can stand it. Grok if I need to live in the repo for hours.
Gemini when I want more room than Fable or Astra and I can live with a weaker thinking model.
Open source for local-ish work, experiments, and anything I do not want to send to the expensive labs.
Fall did not invent a single best model. It invented a model that is too good to ignore and too expensive to live in, and it left Grok as the thing I actually leave open.
That is the board.
Article FAQ
Article takeaways
- What is the best LLM for coding in fall 2026?
- It still depends on the job. OpenAI Astra is #1 for me on intelligence and wide problem handling, and last on usage because of cost. Grok 4.6 is #1 on usable volume and the model I actually live in. Anthropic Fable 5.1 sits between them on hard work.
- Which coding LLM has the most generous usage allowance?
- Grok 4.6 is first for me, by a lot. Gemini is next, ahead of Anthropic and OpenAI. Anthropic Fable 5.1 is second last. OpenAI Astra is last. The smartest model is the one I can least afford to leave on.
- Which LLM is smartest for coding right now?
- OpenAI Astra. It is not a small step over the rest of the board. Anthropic Fable 5.1 is second. Grok 4.6 is third. Gemini is last on this list for me.
- Which LLM handles wide coding problems best?
- Same order as intelligence: OpenAI Astra, Anthropic Fable 5.1, Grok 4.6, then Gemini. Astra holds a messy, multi-file job together better than anything else I have used. The bill is the reason it is not my default.
- What about open source models for coding?
- Qwen is still first among the open models I use. DeepSeek is next. Bonsai and Muse Spark are on the board now. They are not beating Astra. They are good enough that the open list is getting crowded.